
Data Science & ML · AI & Agents
Resume Analysis with NLP and LLMs
By David Gadyan · Published · Updated · Client: Alejandra Leibovich
NLP and LLM analysis of two groups of CVs, high-value and low-value prospect candidates, to surface the patterns, similarities and differences that are not obvious on a read-through. Starting from a client-labelled set of around 30 CVs, I ran exploratory analysis, engineered features and tuned a high-accuracy classifier in Python.
The problem
The client had two sets of resumes, high-value prospect candidates and low-value ones, and wanted to know what actually separates them. The differences were not obvious on a read-through, so the brief was to apply NLP and AI tooling to find the hidden patterns, similarities and differences between the two groups and, ideally, to predict which group a new CV belongs to.
What I built
- Exploratory data analysis over both groups as the first step, to identify relationships and patterns in the text before touching a model.
- Feature engineering driven by those EDA insights, turning the CV text into signals the model could learn from.
- A classification model built with NLP and LLM (ChatGPT) tooling that separates high-value from low-value candidates.
- Parameter tuning against the labelled set to reach high accuracy.
Outcome
The client provided a labelled set of around 30 CVs, which made the EDA and modelling far more reliable than an unlabelled corpus would have. The insights from that analysis powered the feature engineering and tuning, and the resulting model separates the two candidate groups with high accuracy, giving the client an explicit picture of what distinguishes them.
Related projects
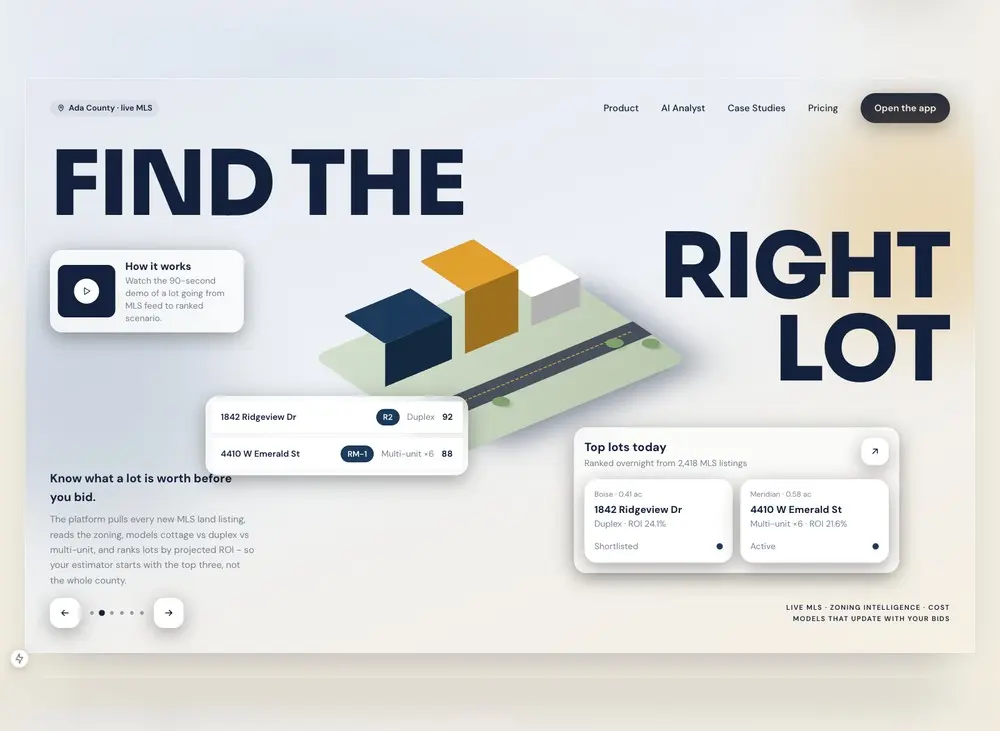
AI Real Estate Lot Analysis Platform for a Residential Builder
AI & Agents · Full-Stack & UI/UX · Data Science & ML
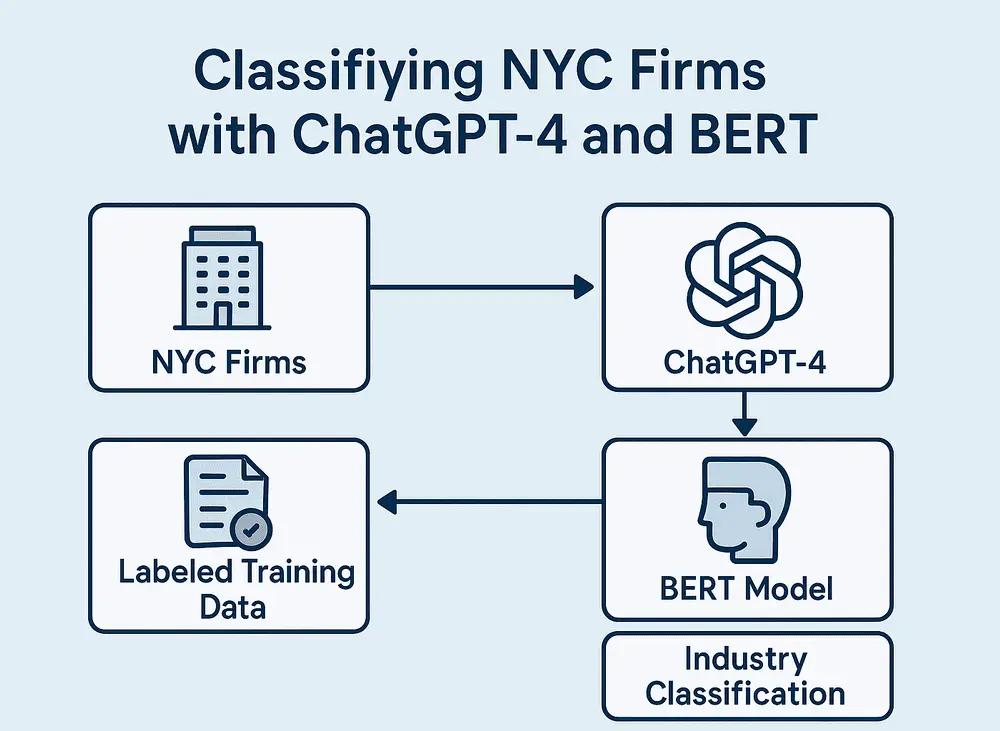
Industry Classification of Firms (BERT + GPT-4 Labelling)
Data Science & ML · AI & Agents
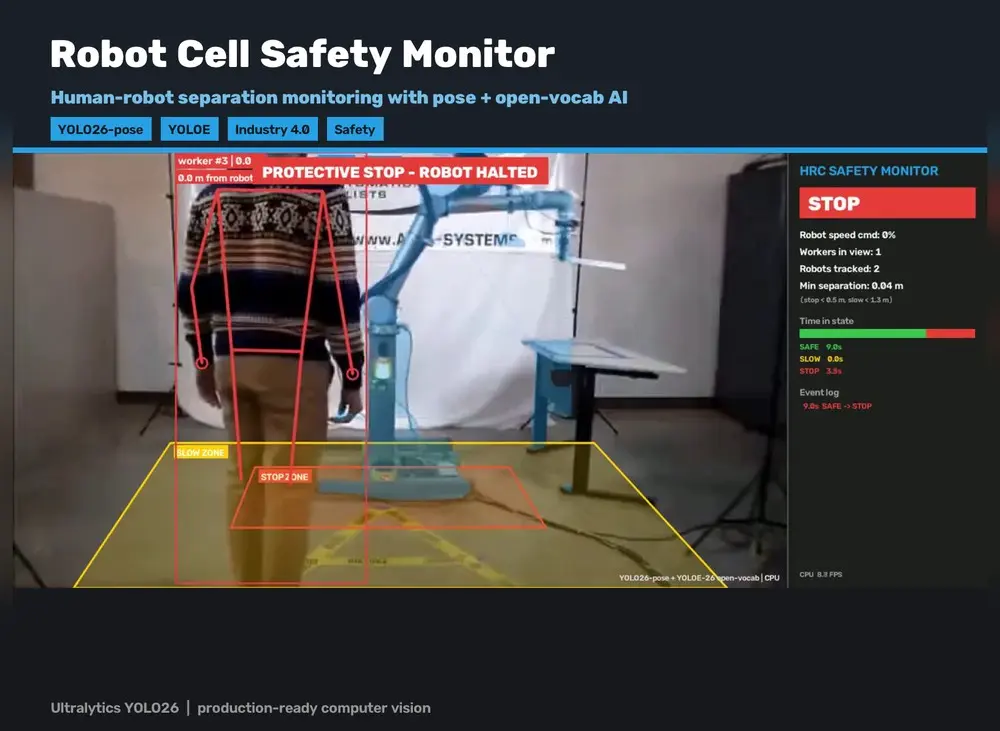
Computer Vision with YOLO26/27: Three Edge-Ready Demos
Computer Vision & Generative Media · Data Science & ML · Cloud, DevOps & LLMOps