
AI & Agents · Databases & Data Engineering · Cloud, DevOps & LLMOps
Crypto Regulation RAG Chatbot (GPT-4 + Pinecone)
By David Gadyan · Published · Updated
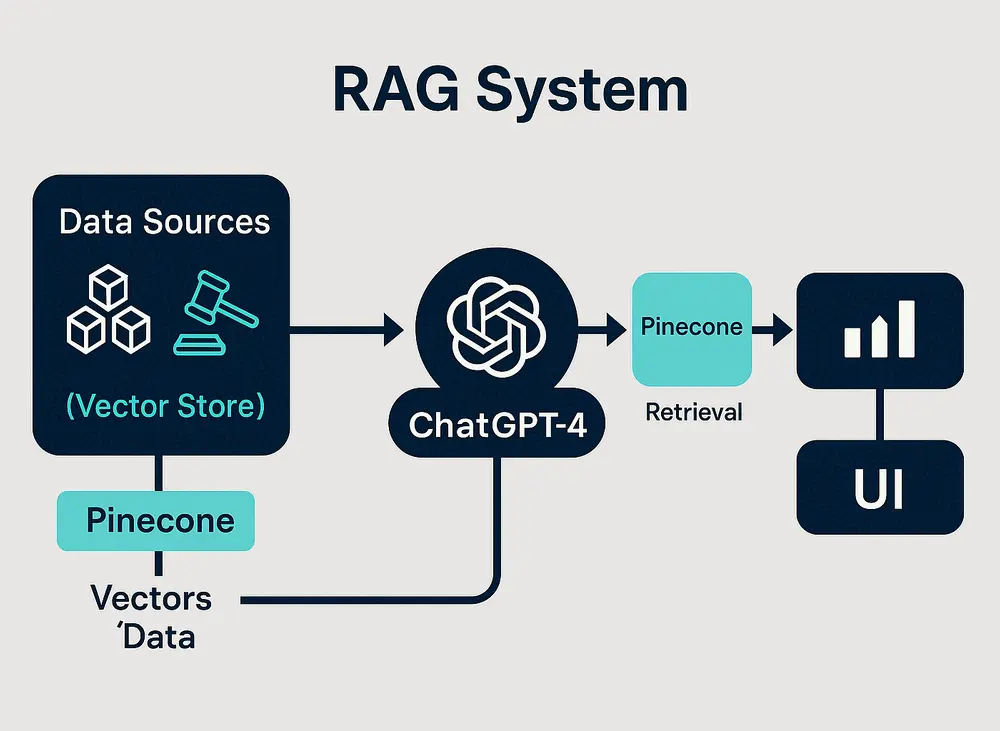
RAG research assistant over 2024 blockchain and crypto regulation across multiple jurisdictions. LangChain pipelines embed PDFs, CSVs, HTML and plain text into a Pinecone vector store, GPT-4 answers jurisdiction-specific legal questions with inline source citations in a Streamlit UI, and the whole thing ships with Docker configuration and deployment scripts so other teams can adapt it.
The problem
Crypto and blockchain regulation moved fast in 2024 and differs by jurisdiction, and the primary sources are scattered across scanned PDFs, CSV tables, HTML pages on sites such as Global Legal Insights and plain-text notes. Answering one question meant reading across all of them and still not being sure which document a claim came from. The goal was a chatbot that answers jurisdiction-specific legal questions in seconds and shows the source for every answer.
What I built
- A LangChain back end that embeds legal and regulatory texts into vectors and indexes them in Pinecone for sub-second retrieval.
- GPT-4 as the generation backbone, with prompts that combine the retrieved context with the user's question so answers stay grounded in the indexed law.
- A Streamlit front end: a conversational UI where users ask jurisdiction-specific questions and see source citations inline.
- Ingestion pipelines for PDFs, CSVs, HTML and plain text, including automated OCR for scanned PDFs, CSV table parsing and HTML scraping from Global Legal Insights.
- Vector-store tuning: embedding dimensions and Pinecone index parameters chosen for cost-effective storage and fast similarity search at scale.
- Packaging with deployment scripts, Docker configuration and a README, plus a connector layer designed so databases, APIs or streaming sources can be added with minimal code changes.
Data and infrastructure
The retrieval layer is what makes the answers trustworthy. Each document is embedded and stored in Pinecone with its source reference, which is what lets the UI cite where a passage came from. Tuning the embedding dimensions and index parameters kept storage cheap without slowing similarity search. The app runs on Streamlit Cloud, and the Docker configuration and scripts mean a team can equally deploy it on its own infrastructure.
Outcome
Sub-second retrieval over the regulatory corpus, multi-format ingestion with OCR, and an inline citation on every answer. Because the solution ships as a documented, containerised package with an extensible connector layer, other teams can point it at their own legal or policy documents instead of starting from scratch.
Related projects
AI Lead Scoring & Churn Detection Engine (S1mple.ai)
AI ERP & SaaS · AI & Agents · AI Marketing & Analytics · Databases & Data Engineering
Virgil.ai: Agentic Health-Insurance Assistant
AI & Agents · AI ERP & SaaS · Cloud, DevOps & LLMOps · Security & Compliance
Multilingual Text Generation: Mistral 7B Fine-Tuning & API
AI & Agents · Cloud, DevOps & LLMOps